Tip Of AI
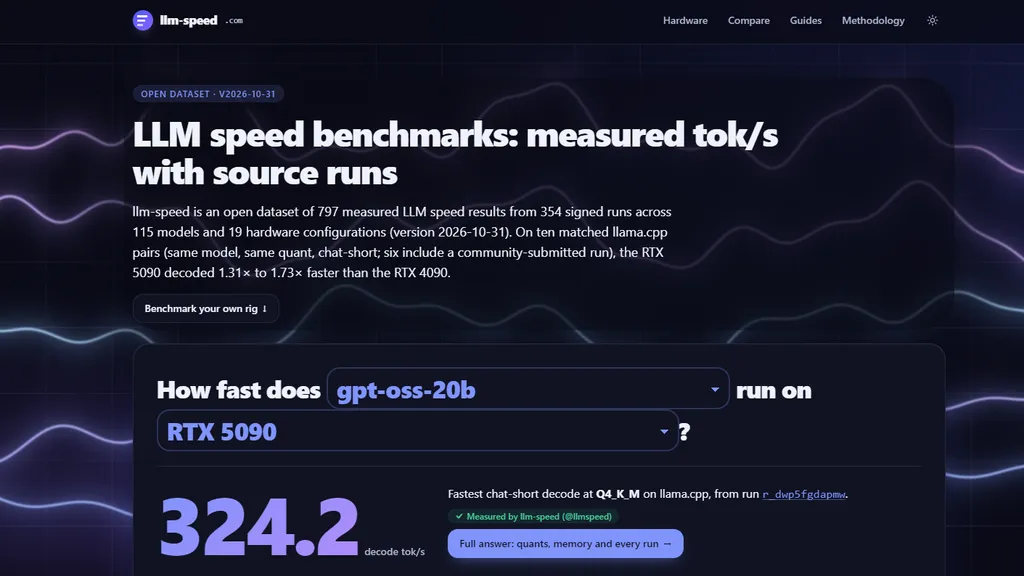
Discover what you can do with AI
llm speed is an open benchmark platform and command line tool for measuring the performance of large language models across different computers graphics cards operating systems model formats and inference backends. It focuses on practical inference speed and records decode tokens per second prefill performance and time to first token. Users can install the tool with pipx and run the benchmark suite on their own machines using installed models and supported backends. The dataset contains 751 measured results from 335 signed runs covering 106 models and 18 hardware configurations. Each result is linked to a source run so users can inspect its provenance. The website provides a leaderboard speed cheatsheet hardware comparisons buying guides methodology information and downloadable CSV data. It also supports macOS Linux and Windows together with GitHub Actions for continuous or nightly benchmarking. Example results include a fastest signed local run of 324 tokens per second for gpt oss 20b on an RTX 5090. Matched llama cpp comparisons show the RTX 5090 decoding between 1.31 and 1.73 times faster than the RTX 4090. The project code is available under the Apache 2.0 license and its data uses the CC BY 4.0 license.